Dual Sequential Monte Carlo
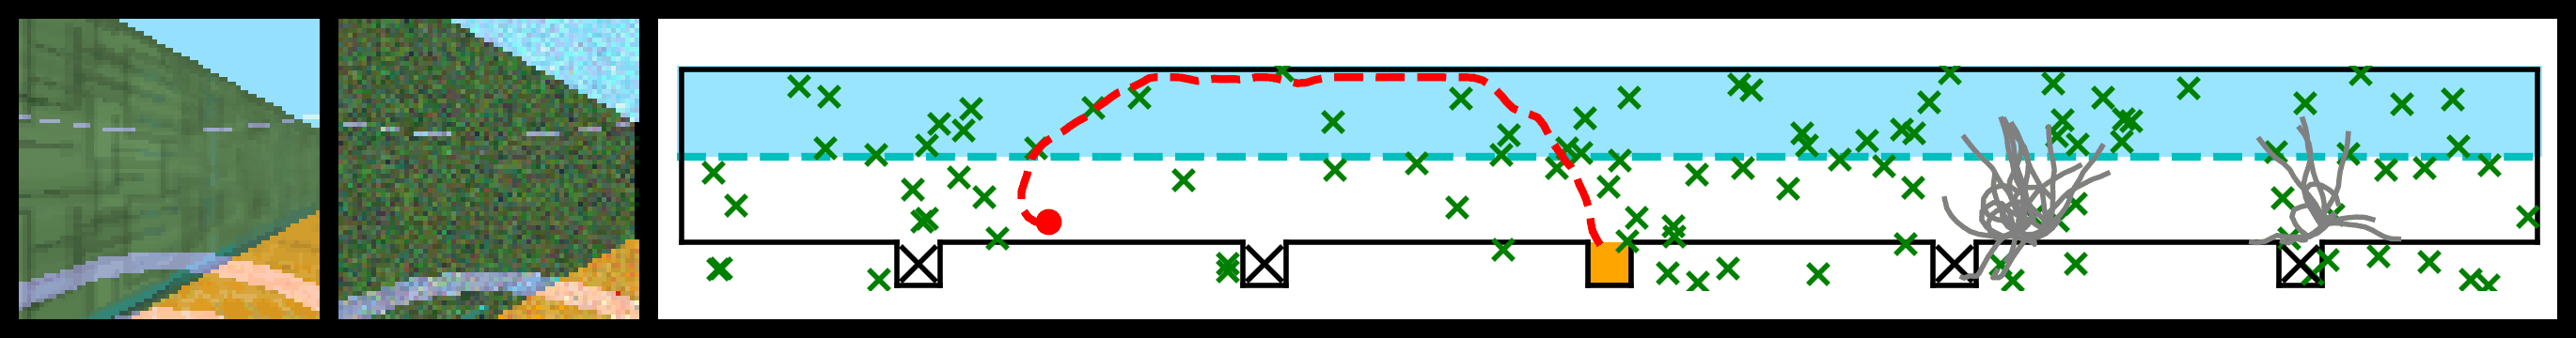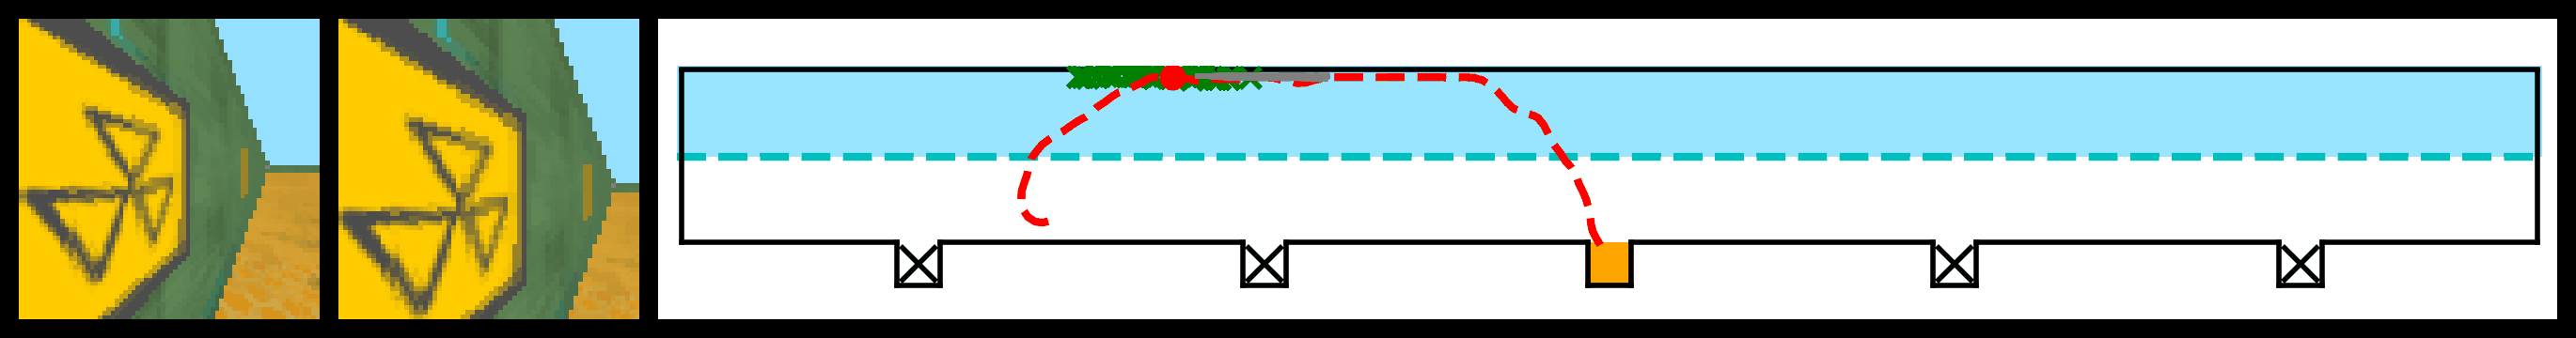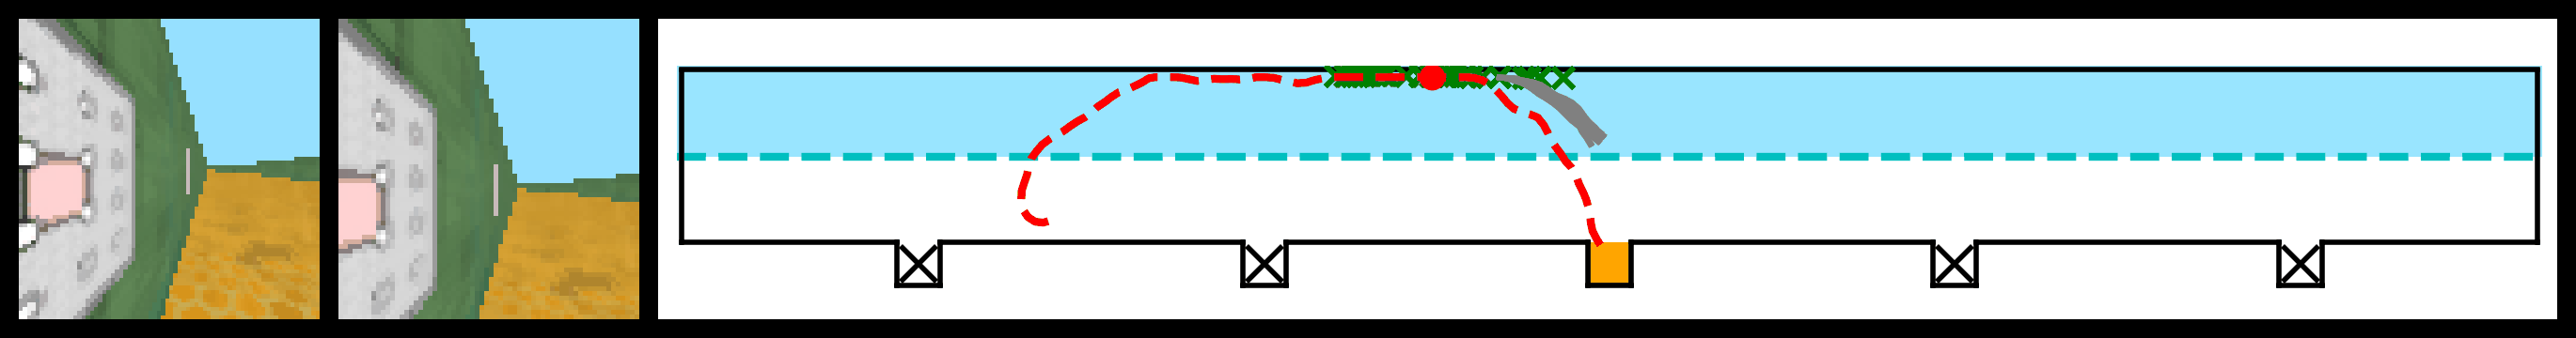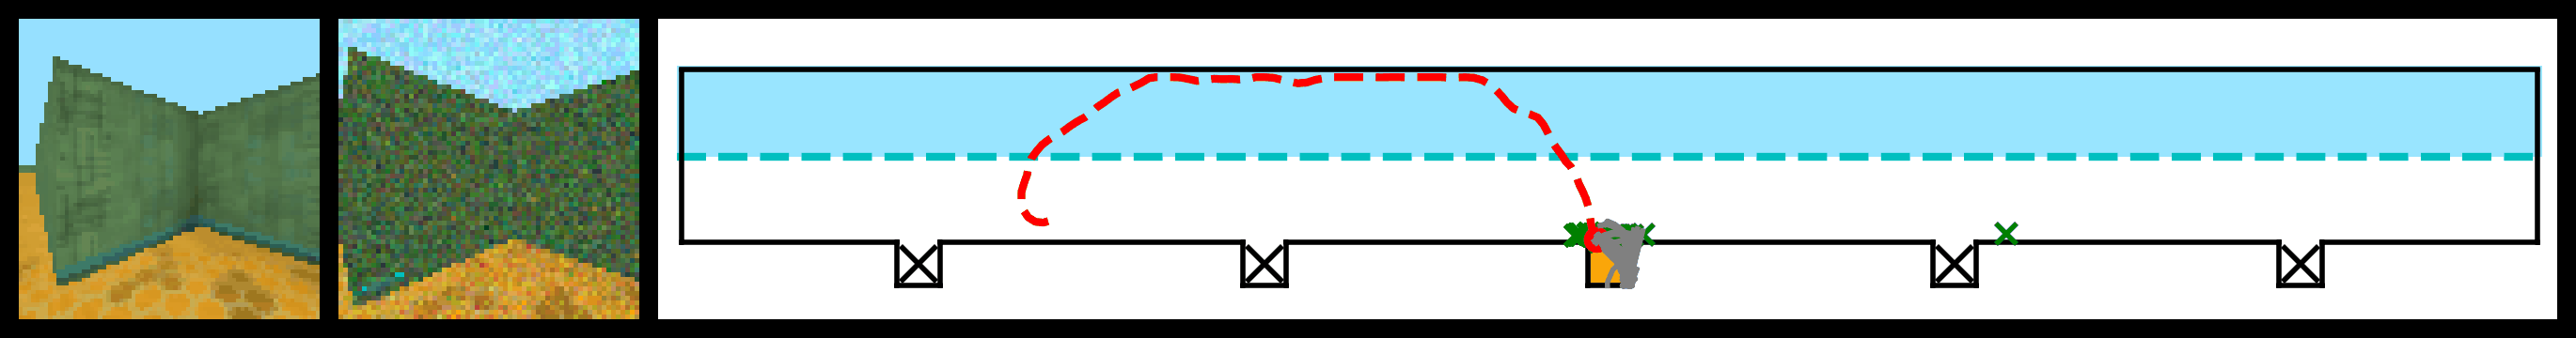
Figure 1: Visualization of DualSMC's planning in a 3D light-dark environment simulated by DeepMind Lab. The agent receives noisy(clear) observation in lower(upper) maze. From left to right are the ground truth observation, the agent's observation, and the particle distribution (marked by green crosses) and planning trajectory (marked in grey).
Overview
We present the DualSMC network that solves continuous POMDPs by learning belief representations and then leveraging them for planning. It is based on the fact that filtering, i.e. state estimation, and planning can be viewed as two related sequential Monte Carlo processes, with one in the belief space and the other in the future planning trajectory space. In particular, we first introduce a novel particle filter network that makes better use of the adversarial relationship between theproposer model and the observation model. We then introduce a new planning algorithm over the belief representations, which learns uncertainty-dependent policies. We allow these two parts to be trained jointly with each other.
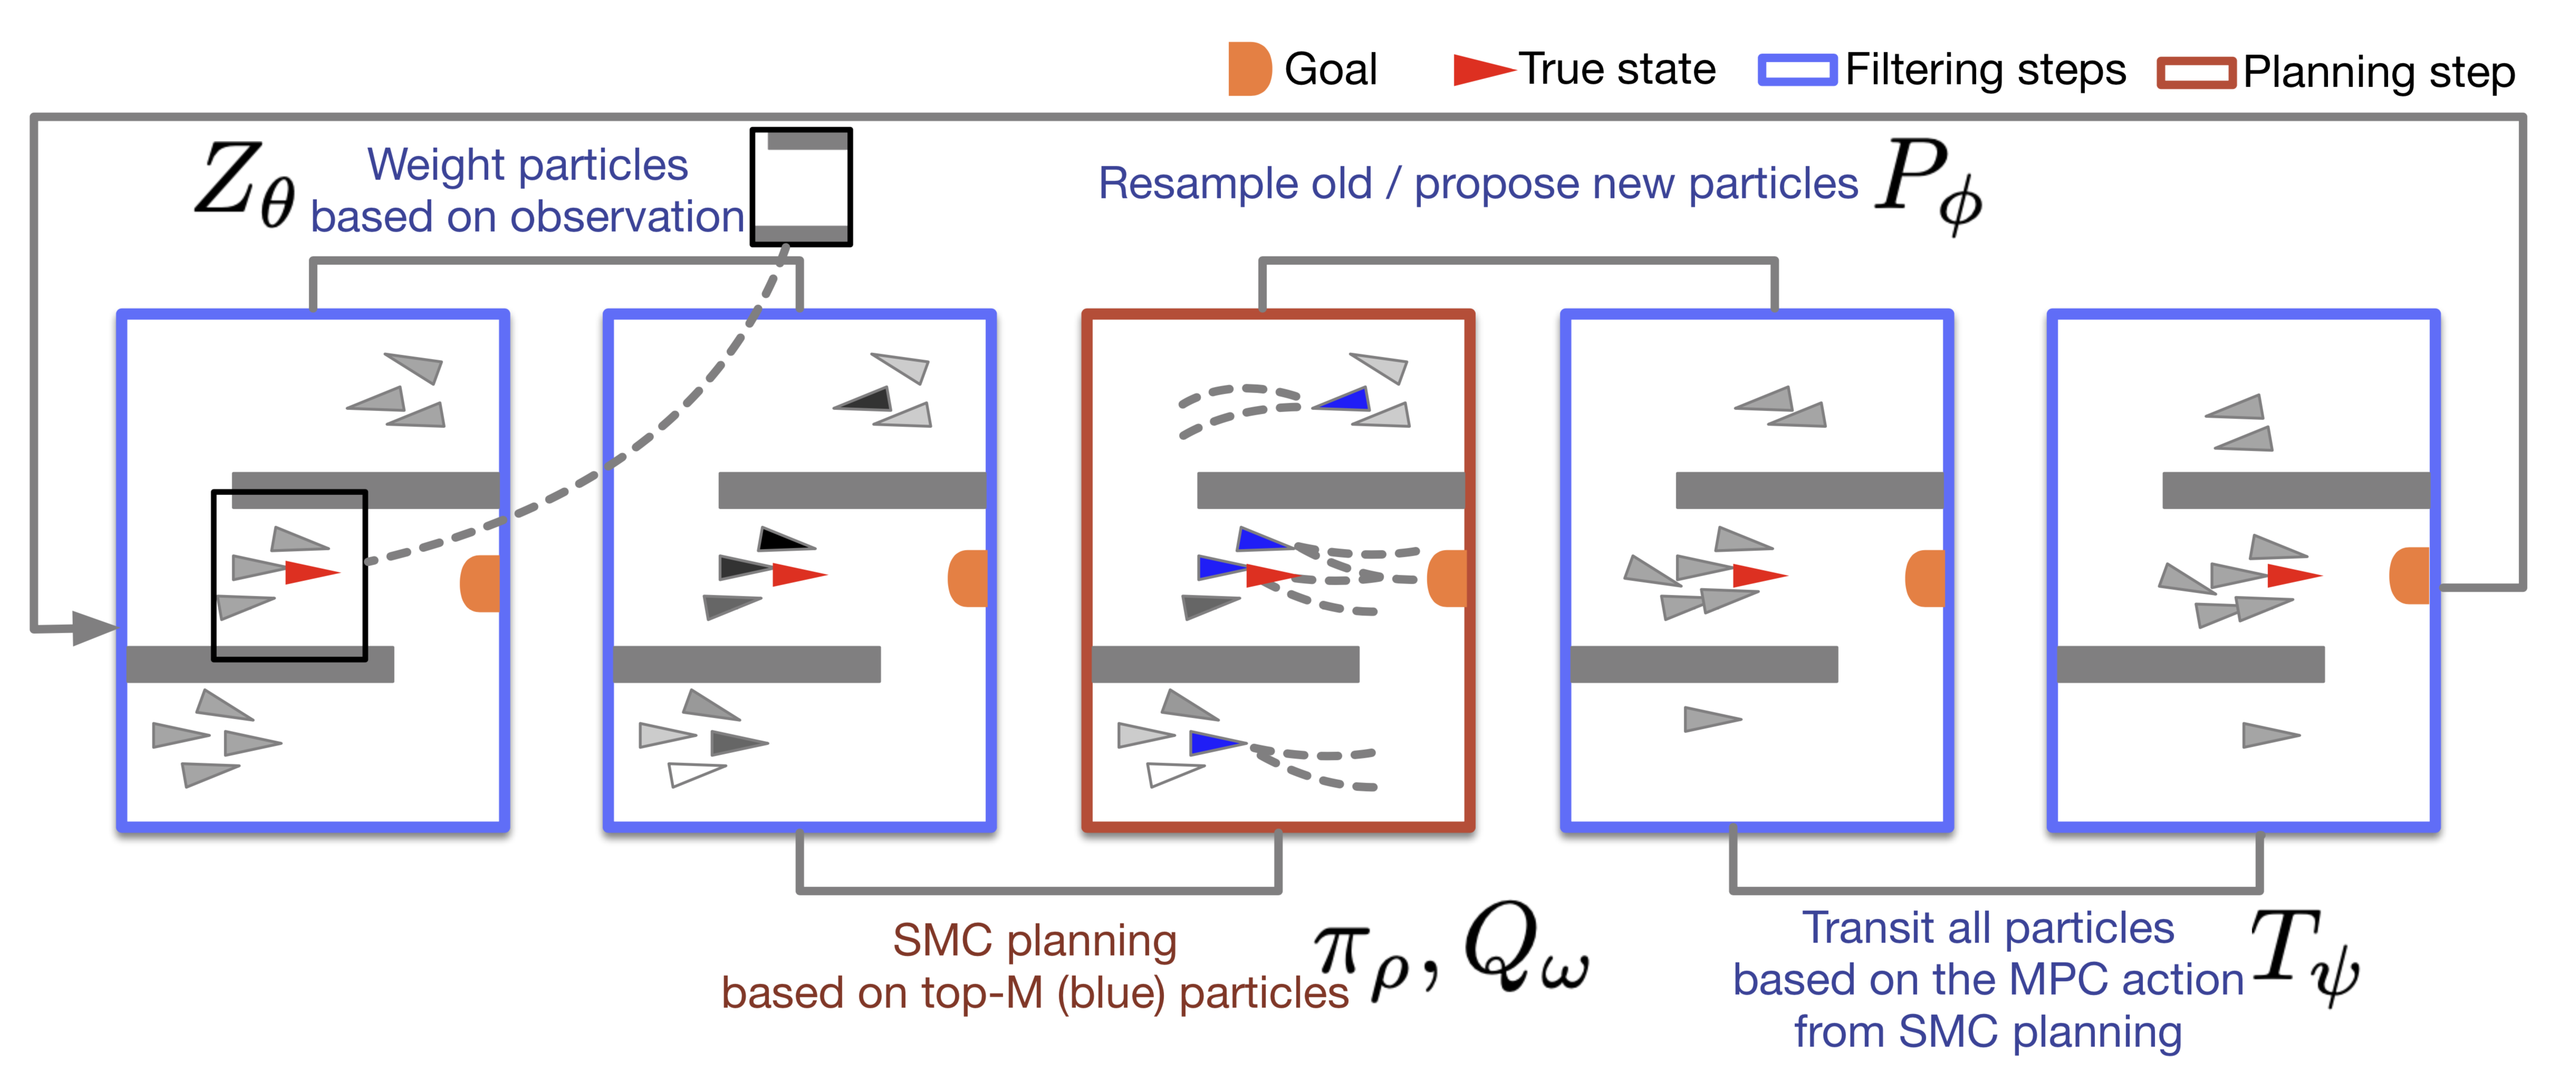
Figure 2: The pipeline of DualSMC. The planner and filter are linked via belief representatives.